research1 source
Perturbation Probing Reveals Fragility of LLM Safety Mechanisms
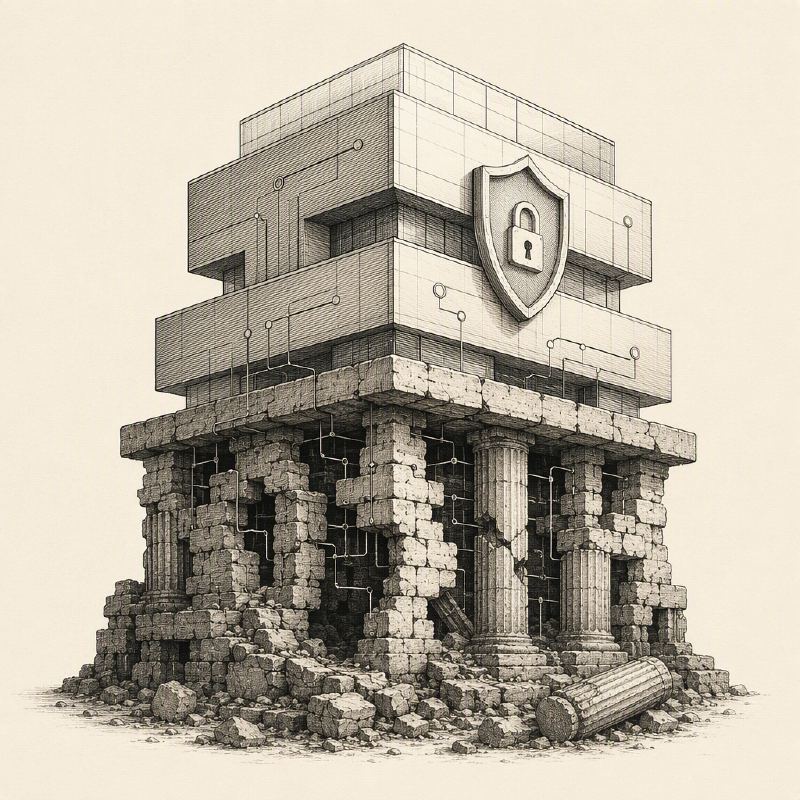
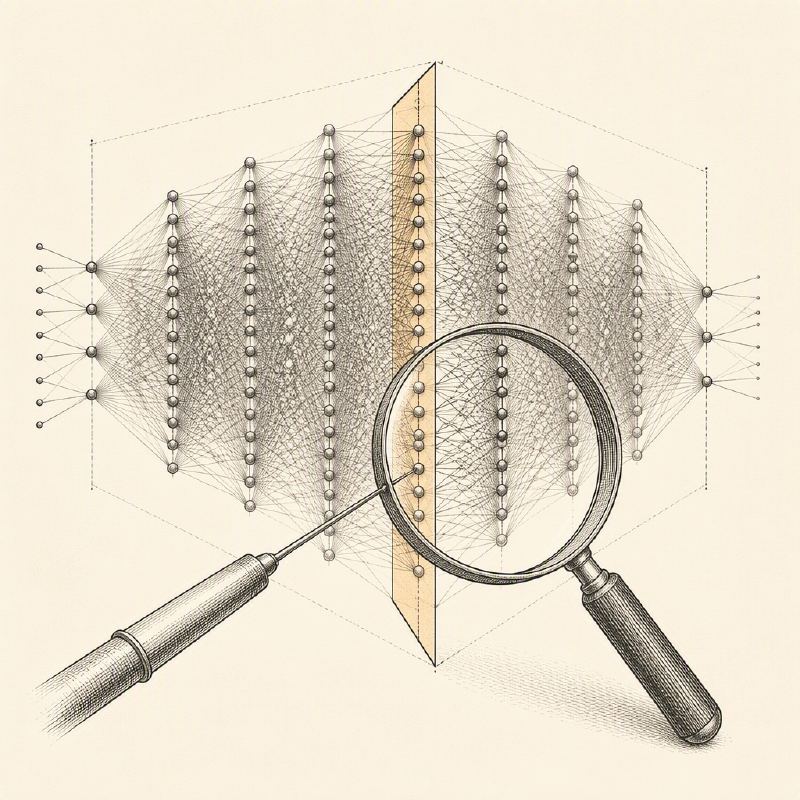
New research introduces 'Perturbation Probing,' a method to diagnose LLM safety vulnerabilities, finding that AI safety mechanisms reside in a thin neural layer susceptible to manipulation.
Aug 28, 2026