
Cloudflare Unveils Clairic AI Model for Cost-Effective Data Extraction
Cloudflare introduces Clairic, a new AI extraction model designed to significantly reduce costs and improve efficiency for tasks like invoice processing by avoiding token generation.
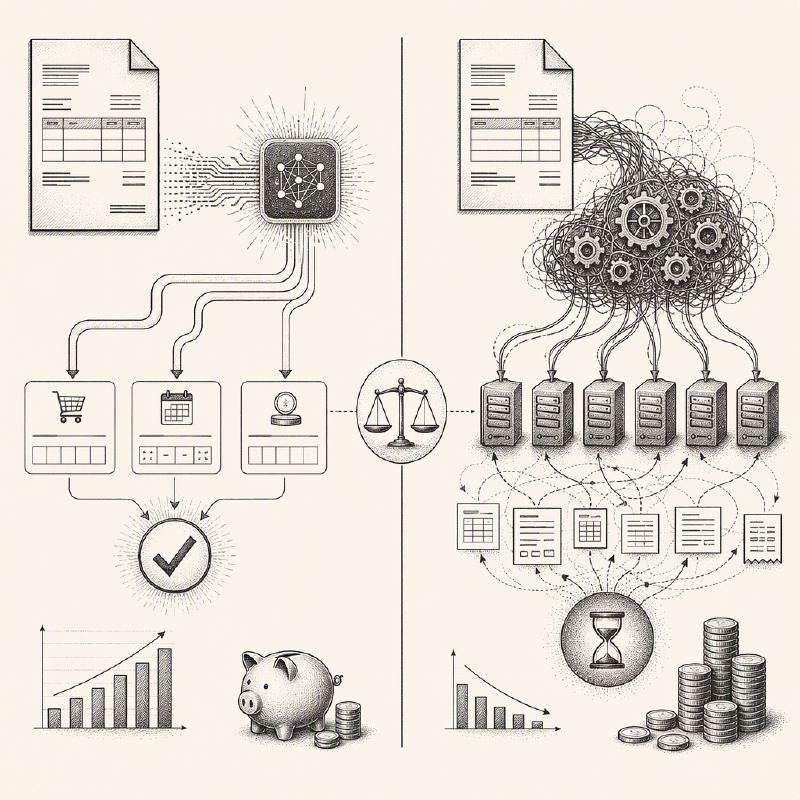
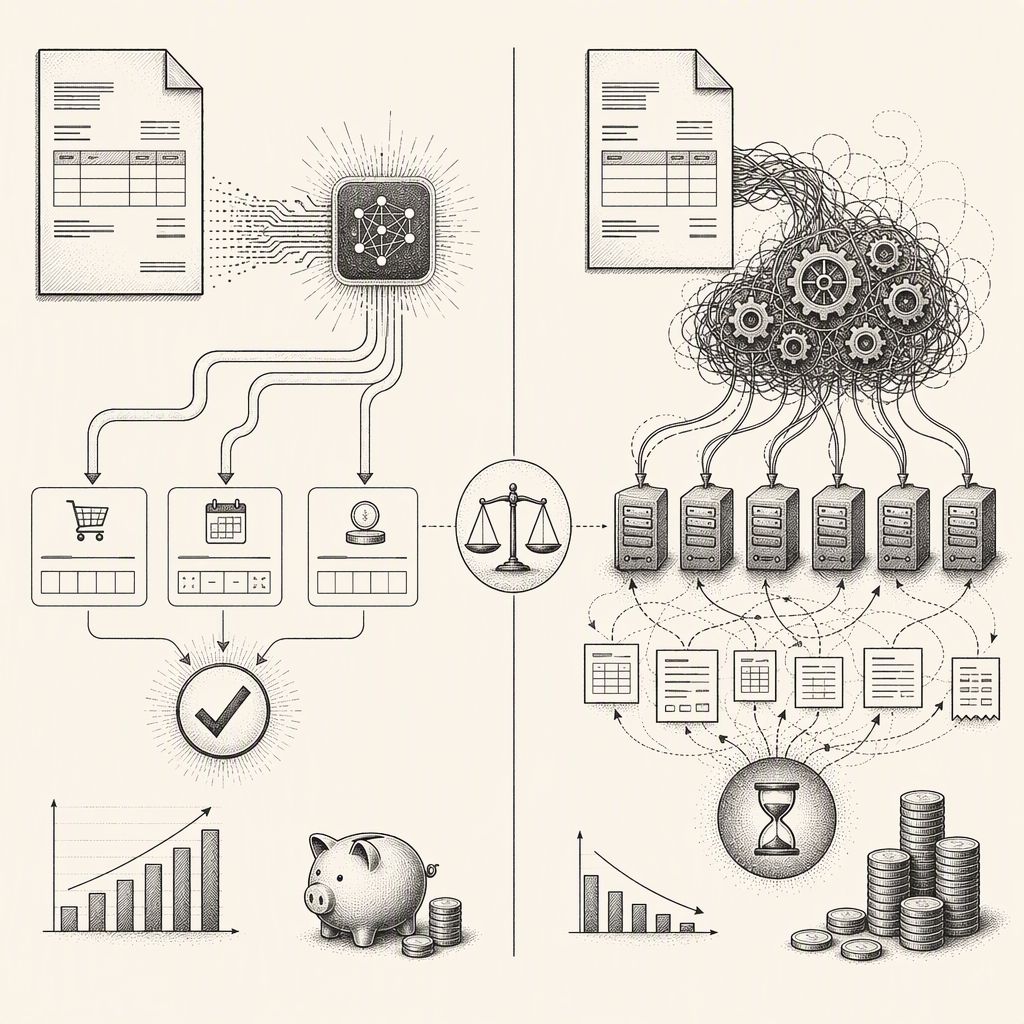
Cloudflare has announced the preview of Clairic, a novel AI extraction model engineered to process text and images efficiently without generating tokens. This innovation aims to provide a more cost-effective and faster alternative to using large language models (LLMs) for data extraction tasks, such as parsing invoices and extracting key information.
In practical tests conducted by Cloudflare, a workflow utilizing Clairic demonstrated substantial improvements over LLM-centric pipelines. For a damaged-product support claim, the Clairic-based approach completed the task in 19.3 seconds, a significant reduction from the 61.7 seconds required by an LLM-heavy process. Furthermore, the Clairic pipeline was 49% cheaper to operate, highlighting its economic advantages.
The challenge Clairic addresses is the common developer practice of relying on LLMs for structured data extraction from unstructured inputs like invoices. While LLMs can perform these tasks, they often introduce complexities such as emitting broken JSON, misreading digits, or returning incomplete data without clear source pointers. Developers typically compensate by implementing additional parsers, schema validation, and retry mechanisms, all while incurring costs for output tokens for every extracted field.
Clairic operates on Cloudflare's Workers AI platform under the identifier @cf/cloudflare/clairic, with plans to make its weights publicly available. Developers can submit text, up to four images, and a list of desired named fields with specified types (e.g., number, date, list). The model then returns the extracted values with their corresponding types, or null if not found. Scalar answers include a confidence score and a probability of the value being absent (p_null), while extracted text provides character offsets for precise location.
Cloudflare's testing revealed Clairic's capabilities and limitations. In one instance, it correctly inferred a total of $701.10 from a customer email by adding a $649.00 price and $52.10 tax, even though the total was not explicitly stated. It also accurately identified the absence of a tracking number, returning null with a high p_null probability. However, the model's architecture prioritizes well-formed answers over absolute correctness, meaning longer chains of arithmetic or complex table sums are not its forte, and Cloudflare advises using traditional code for such operations.
Further evaluations included forecasting the next day's TSA checkpoint counts at U.S. airports over 21 consecutive days. Clairic's forecasts missed the actual counts by an average of 3.3%, with 17 out of 21 actual counts falling within its predicted 80% confidence interval, indicating good calibration. However, the model struggled with holiday periods like Columbus Day, where historical traffic data provided no context for the anomaly.
Cloudflare acknowledges that Clairic is an "early checkpoint" and not a complete solution for all data extraction needs. While single- and two-step extractions appear reliable, complex calculations and forecasting on unfamiliar data can be challenging. The company recommends that developers use code for intricate mathematical operations and be mindful of the model's confidence scores and p_null values to interpret results accurately, especially when dealing with potentially ambiguous data.
The introduction of Clairic represents a significant step towards more efficient and economical AI-powered data processing. By focusing on extraction without token generation and providing clear confidence metrics, Cloudflare aims to empower developers to build more robust and cost-effective applications that leverage AI for understanding unstructured data.