
Cloudflare Basin GA: Serverless Data Platform Built on Open Standards
Cloudflare's data analytics platform, formerly known as the Data Platform, is now generally available as Cloudflare Basin, featuring serverless capabilities built on Apache Iceberg and R2 Object Storage.
Cloudflare has announced the general availability of its serverless data analytics platform, now rebranded as Cloudflare Basin. Previously introduced as the Cloudflare Data Platform during Birthday Week 2025, Basin is designed to ingest, store, and query analytical data efficiently. The platform leverages open standards, specifically Apache Iceberg for its data lake format and Cloudflare's R2 Object Storage for data storage, aiming to provide developers with speed, openness, and cost-efficiency.
Basin comprises three core components. Basin Pipelines, formerly Cloudflare Pipelines, handles data ingestion from sources like Workers, HTTP requests, and Cloudflare Logpush. It transforms this data using SQL and writes it into Apache Iceberg tables stored in R2. Complementing this is Basin Catalog, previously R2 Data Catalog, which manages the metadata for Iceberg tables, ensuring they remain performant and cost-effective through automatic maintenance. Finally, Basin SQL, formerly R2 SQL, offers a serverless, distributed SQL query engine that allows users to directly query their Iceberg tables hosted on Cloudflare.
The development of Basin was driven by two key industry shifts: the rise of Apache Iceberg as an open standard for data lakes, enabling data portability across various query engines, and the increasing adoption of R2 Object Storage due to its lack of egress charges, making data access more practical and economical. Cloudflare's own internal teams, including billing and infrastructure, have adopted Basin for use cases ranging from real-time e-commerce optimization to long-term storage of billing metrics and telemetry analysis.
During its open beta phase, early adopters provided valuable feedback that shaped Basin's evolution. Cloudflare focused on enhancing three key areas: speed, openness, and cost efficiency. Basin is engineered for rapid deployment and query execution, allowing users to set up pipelines and query data in seconds. Its architecture is designed to maintain query performance even as datasets grow, with Basin Catalog optimizing metadata and Basin SQL distributing query tasks across Workers.
The platform's commitment to openness is underscored by its native support for Apache Iceberg. This allows data stored in Basin to be read and written using any Iceberg-compatible engine, such as PyIceberg, DuckDB, Snowflake, and Apache Spark. This data portability, combined with Cloudflare's zero egress fees, empowers developers to access their data from a wide array of tools and platforms without incurring additional costs.
Cost efficiency is another cornerstone of Cloudflare Basin. Its serverless, usage-based pricing model means customers are only billed for the data they ingest, process, or query. This approach makes it accessible for hobby projects with minimal cost while scaling economically for enterprise-level use cases, eliminating concerns about hourly charges or separate infrastructure expenses.
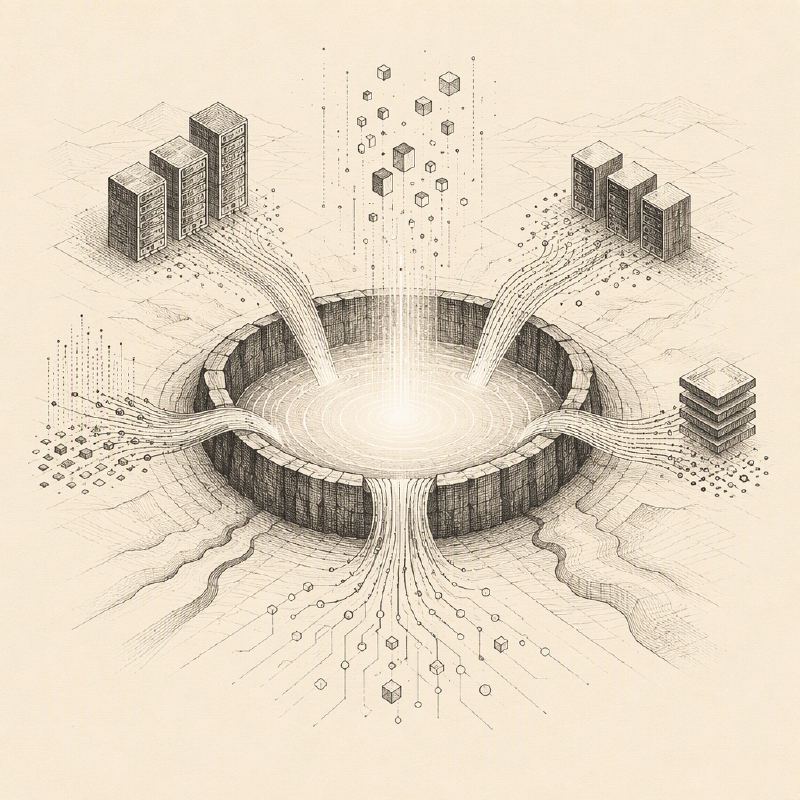
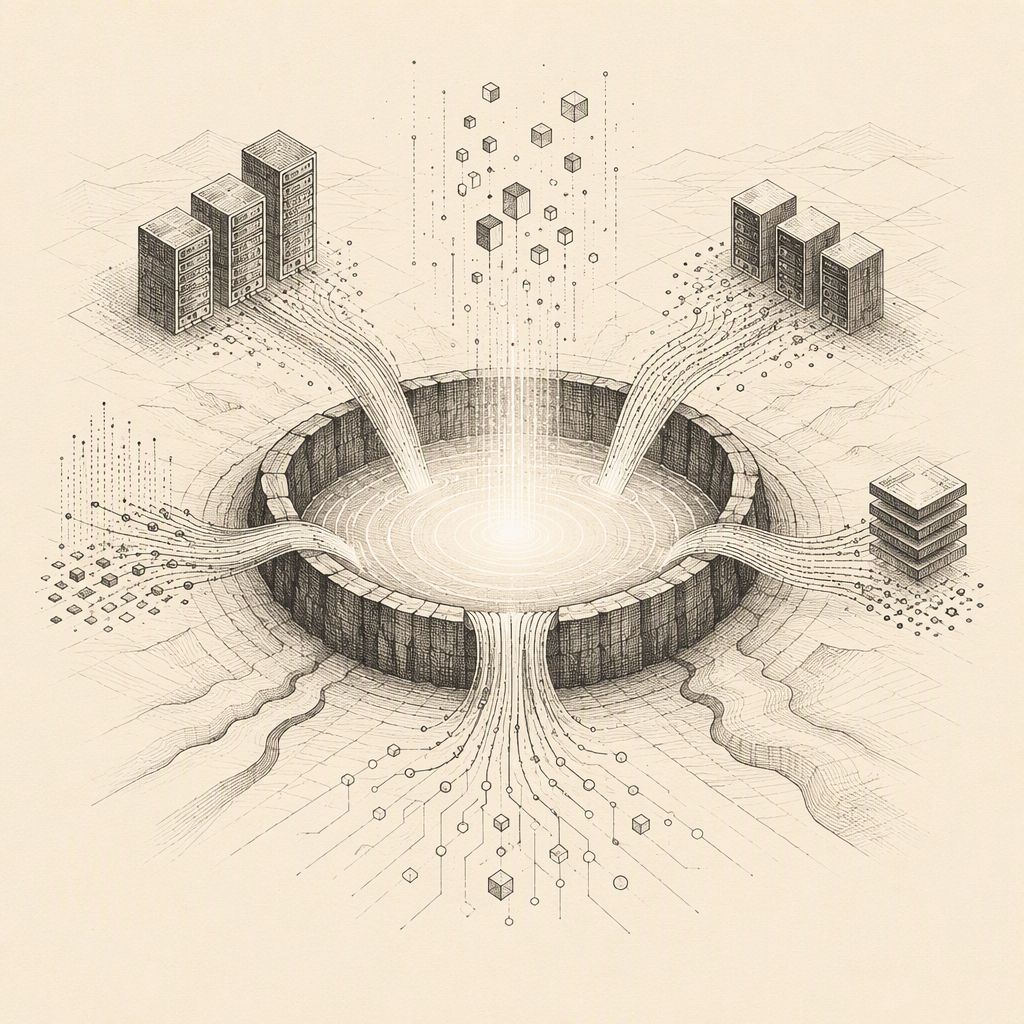
The rebranding to Cloudflare Basin signifies the platform's expanded ambitions and its role as a central hub for data. The name 'Basin' evokes the convergence of multiple rivers into a single point, mirroring how the platform brings together data from various sources for analysis. Cloudflare plans to continue expanding Basin's capabilities, with future developments aimed at covering more aspects of the analytical data lifecycle beyond ingestion, storage, and querying.